Models
Every model you can call, with its price in the unit you are billed in. This page is always current. The Models reference page here reads the same catalog, as of the date shown above its table.
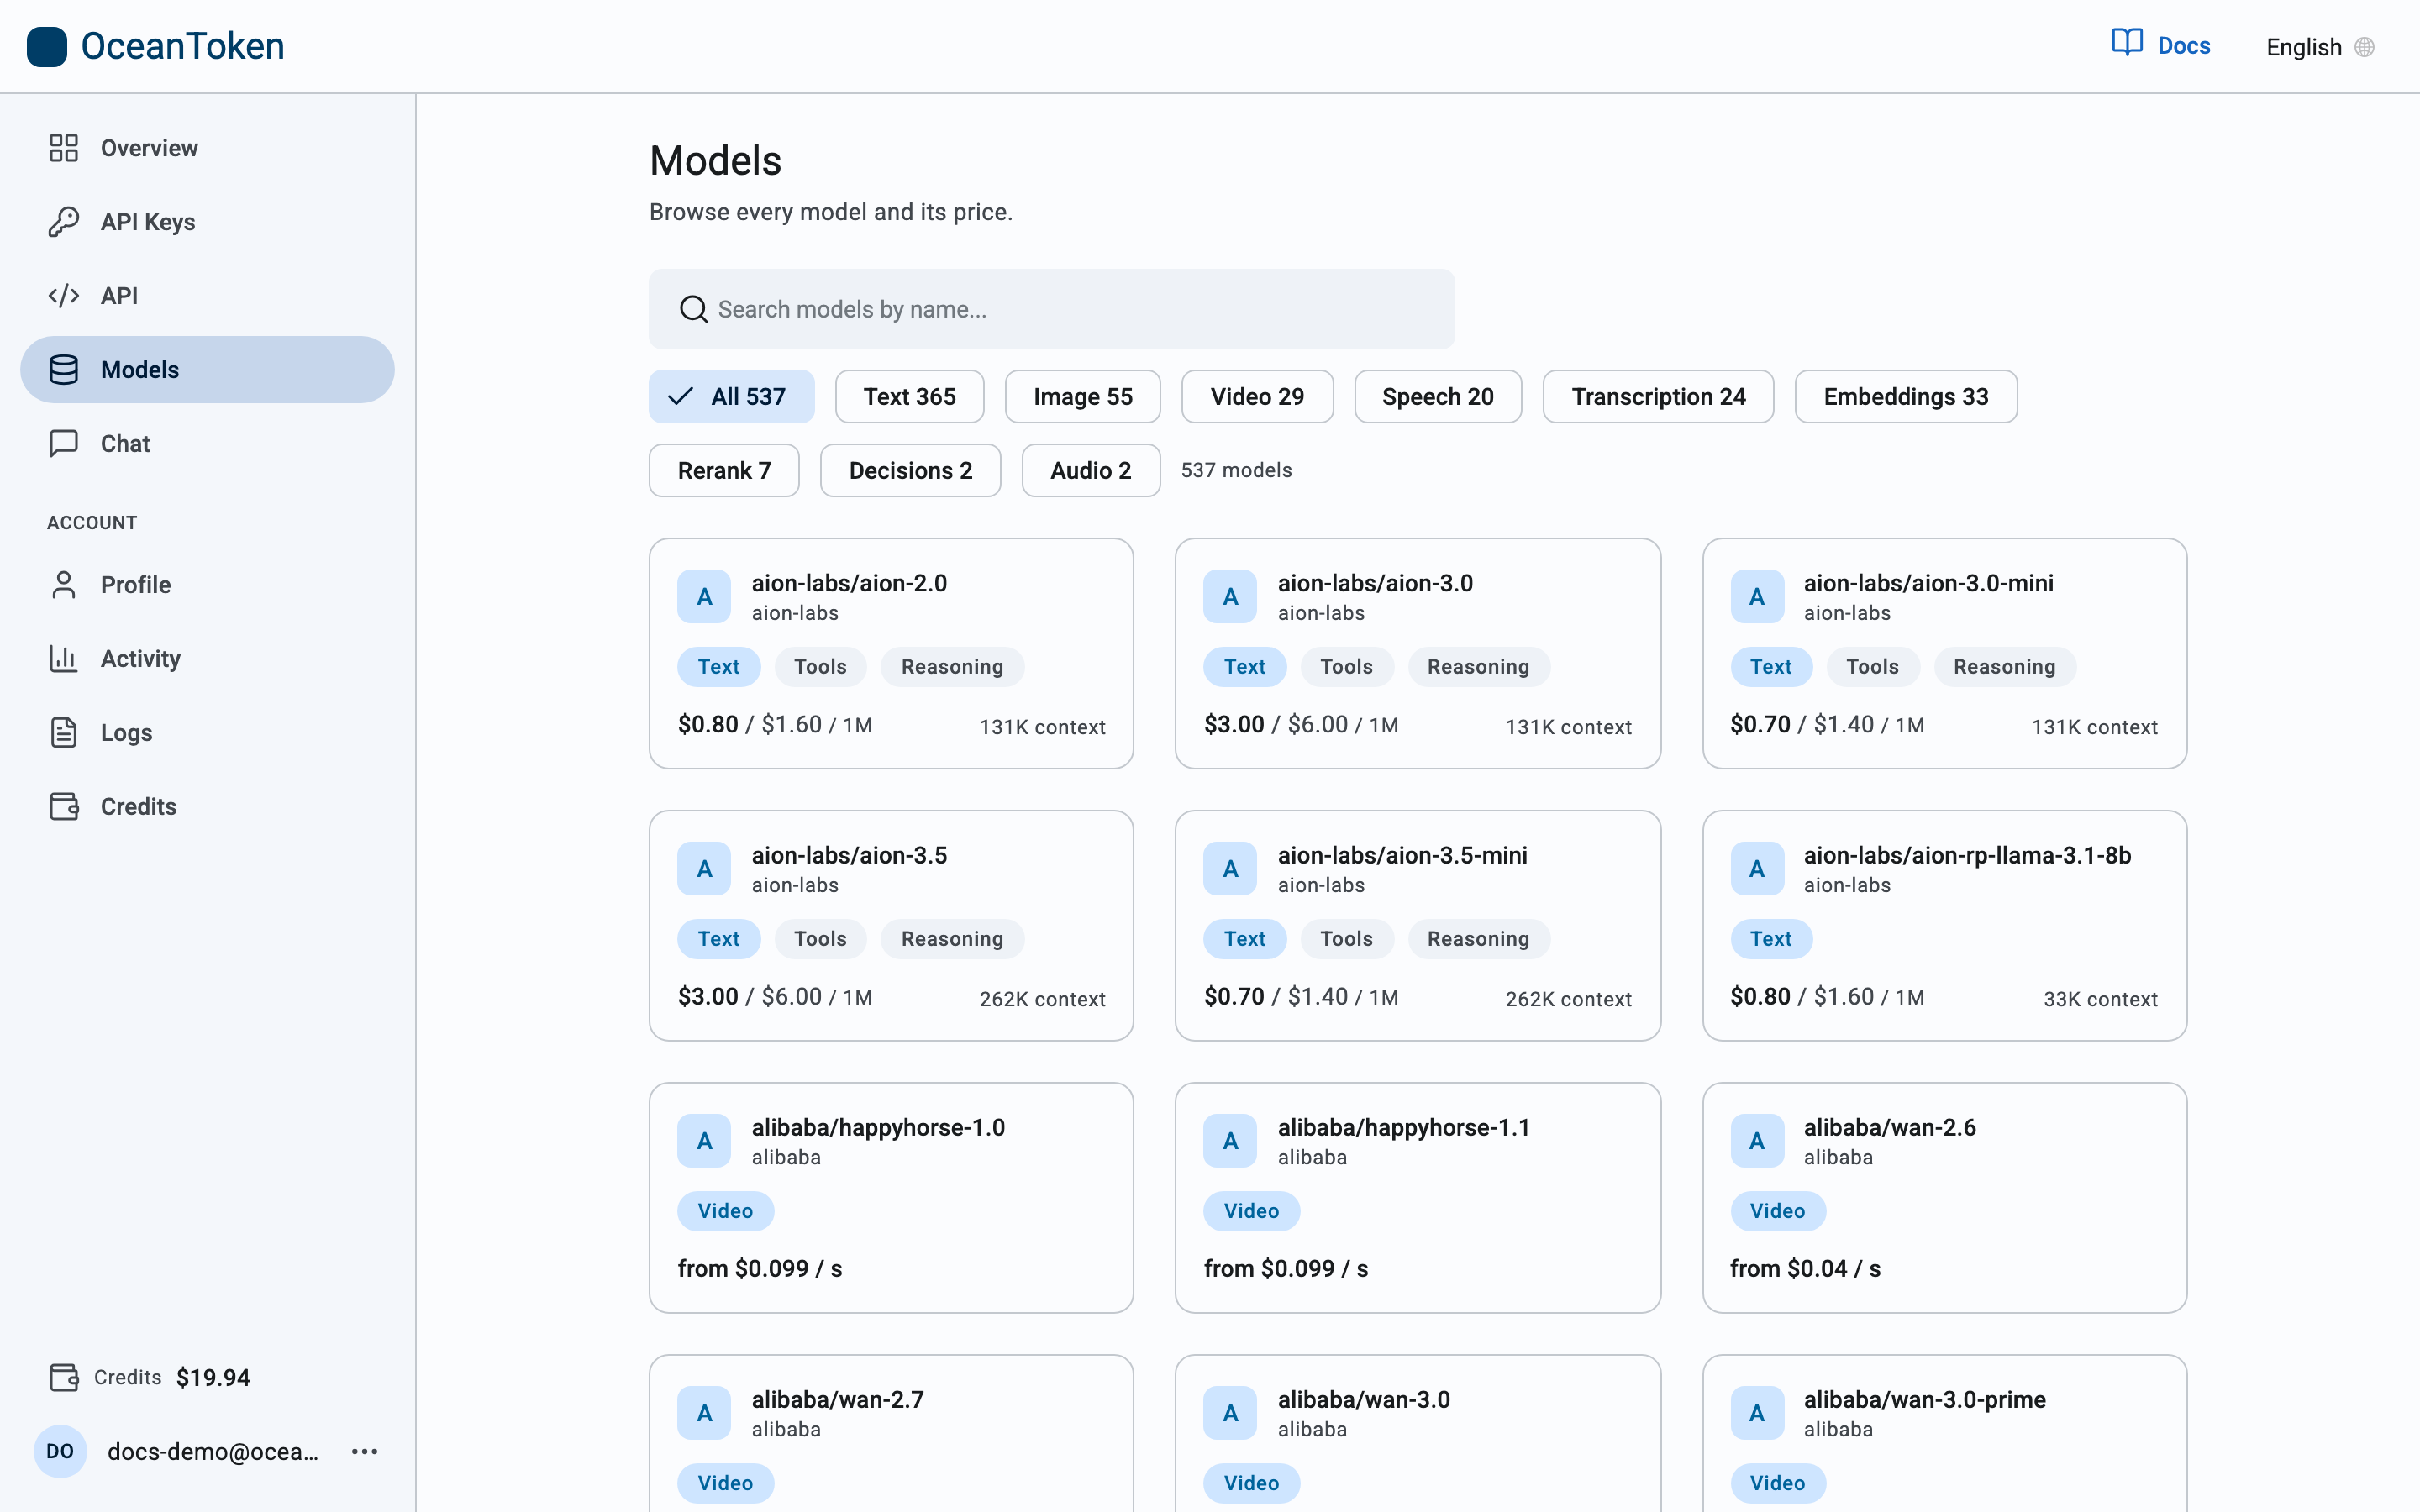
Find a model
- Search by name.
- Filter by type; each chip shows how many models it holds: Text, Image, Video, Speech, Transcription, Embeddings, Rerank, Decisions, Audio.
- Every card shows its capability chips: Tools, Reasoning, Vision.
Read a card
| Shown | Meaning |
|---|---|
$0.85 / $1.70 / 1M | Input and output price per million tokens |
/ image | Price per generated image |
/ megapixel | Image: price per megapixel of output; first MP, then $x / MP when each further megapixel costs less |
/ search unit | Rerank: price per search unit |
/ 1K chars | Speech: price per thousand characters of input text |
/ min | Transcription: price per minute of audio |
from … / s | Video: price per second of output, from the lowest resolution and mode |
| Cached input, Cache write | Price per million prompt tokens read from, and written into, the cache, on models that have them |
| Billed at the model it picks | smart-router: each request is billed at the price of the model it picks |
131K context | The largest input the model accepts, in tokens |
| Free · rate-limited | No charge; throughput is limited and not guaranteed |
| Price TBD | Callable now. Its price has not been published yet, so calls are free until it is; the price applies from the moment it appears here, never retroactively |
The name on the card is the exact model value to send. Opening a model shows every price it has, including the one-hour cache write where there is one. How each kind of model is charged is on the Models reference page.
Typical use: pick a model and try it
Choose Try in playground on a text model to open Chat with it selected.